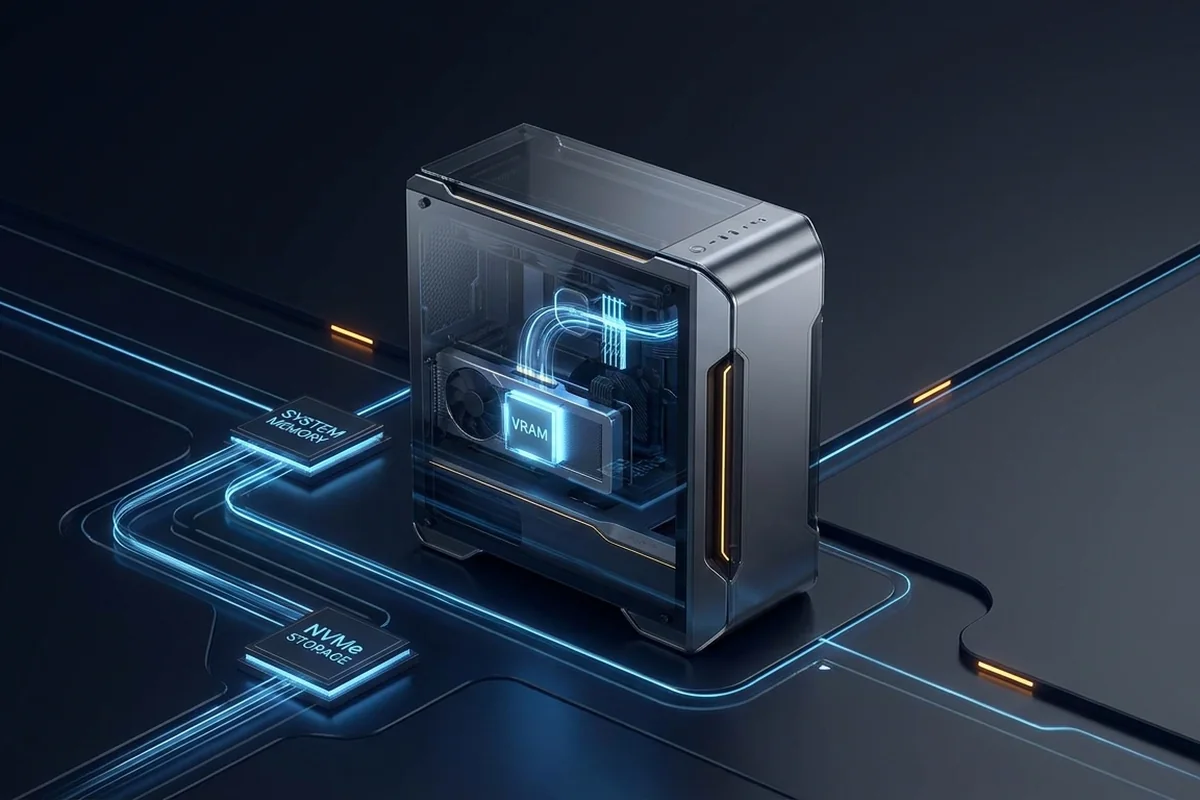
Local AI performance is frequently constrained first by GPU memory capacity, then by memory bandwidth and compute. The CPU, RAM and storage still determine model loading, preprocessing and how efficiently the accelerator stays fed.
Measure the stage that misses its time or capacity target. Do not substitute a gaming percentage for the real project.
Map the processing stages in local AI workloads
Plan a local AI workstation around model fit, VRAM, memory bandwidth and data movement, then measure loading separately from steady throughput.
Signals that support local AI workloads
- A model that does not fit in VRAM can slow dramatically through offload.
- Precision and quantization change both capacity and speed.
- Batch size affects utilization and latency.
- Generation, training and fine-tuning have different hardware profiles.
Benchmark local AI workloads in the real workflow
Test local AI workloads with the following controlled sequence and record the response after each change.
Controlled checks for local AI workloads
- Measure VRAM allocation, GPU utilization and tokens or images per second.
- Separate model-load time from steady inference.
- Watch system RAM and storage traffic during offload.
- Test the exact framework and model family you intend to use.
A workflow-based example
A quantized model exceeds available VRAM by a small margin and offloads layers to system memory. It runs, but throughput falls and transfer activity rises. A GPU with sufficient capacity may help more than one with higher compute but the same memory limit. The exact framework and context size must be part of the test.
Evidence by workflow stage
Use the comparison to distinguish interactive delay, sustained throughput and capacity pressure. They can lead to different fixes.
| AI stage | Primary pressure | Useful metric |
|---|---|---|
| Model load | Storage and system RAM | Seconds to ready state |
| Prompt processing | Compute and memory bandwidth | Tokens per second |
| Generation with offload | VRAM capacity and transfer | Tokens per second plus transfer activity |
Optimize local AI workloads without moving the bottleneck
For local AI workloads, apply the lowest-risk relevant change first and repeat the original measurement before moving on.
Low-risk actions for local AI workloads
- Prioritize enough VRAM for the target model and context.
- Use supported precision or quantization formats.
- Provide adequate system RAM and fast model storage.
- Scale CPU and PCIe resources to multi-GPU or data-preparation needs.
Pipeline distractions to separate
A slow completion time can come from several stages. Clear these alternatives before assigning the delay to one component.
- A model can fit in VRAM while the KV cache or batch does not.
- Slow model loading is a storage symptom, not steady inference throughput.
- Framework and backend support can outweigh nominal GPU compute.
Workflow and workstation questions
Is the fastest gaming GPU always best for AI?
No. VRAM capacity, software support and model precision can matter more than gaming rank.
Can system RAM replace VRAM?
Offload can make a workload run, but it is usually much slower than keeping active data on the GPU.
Does a faster CPU speed up generation?
Only when preprocessing, scheduling or offload is the limiting stage.
Technical sources and further reading
The references below support the specific measurement method or technology discussed for local AI workloads. Check the documented software version and system configuration before transferring a result to another PC.
